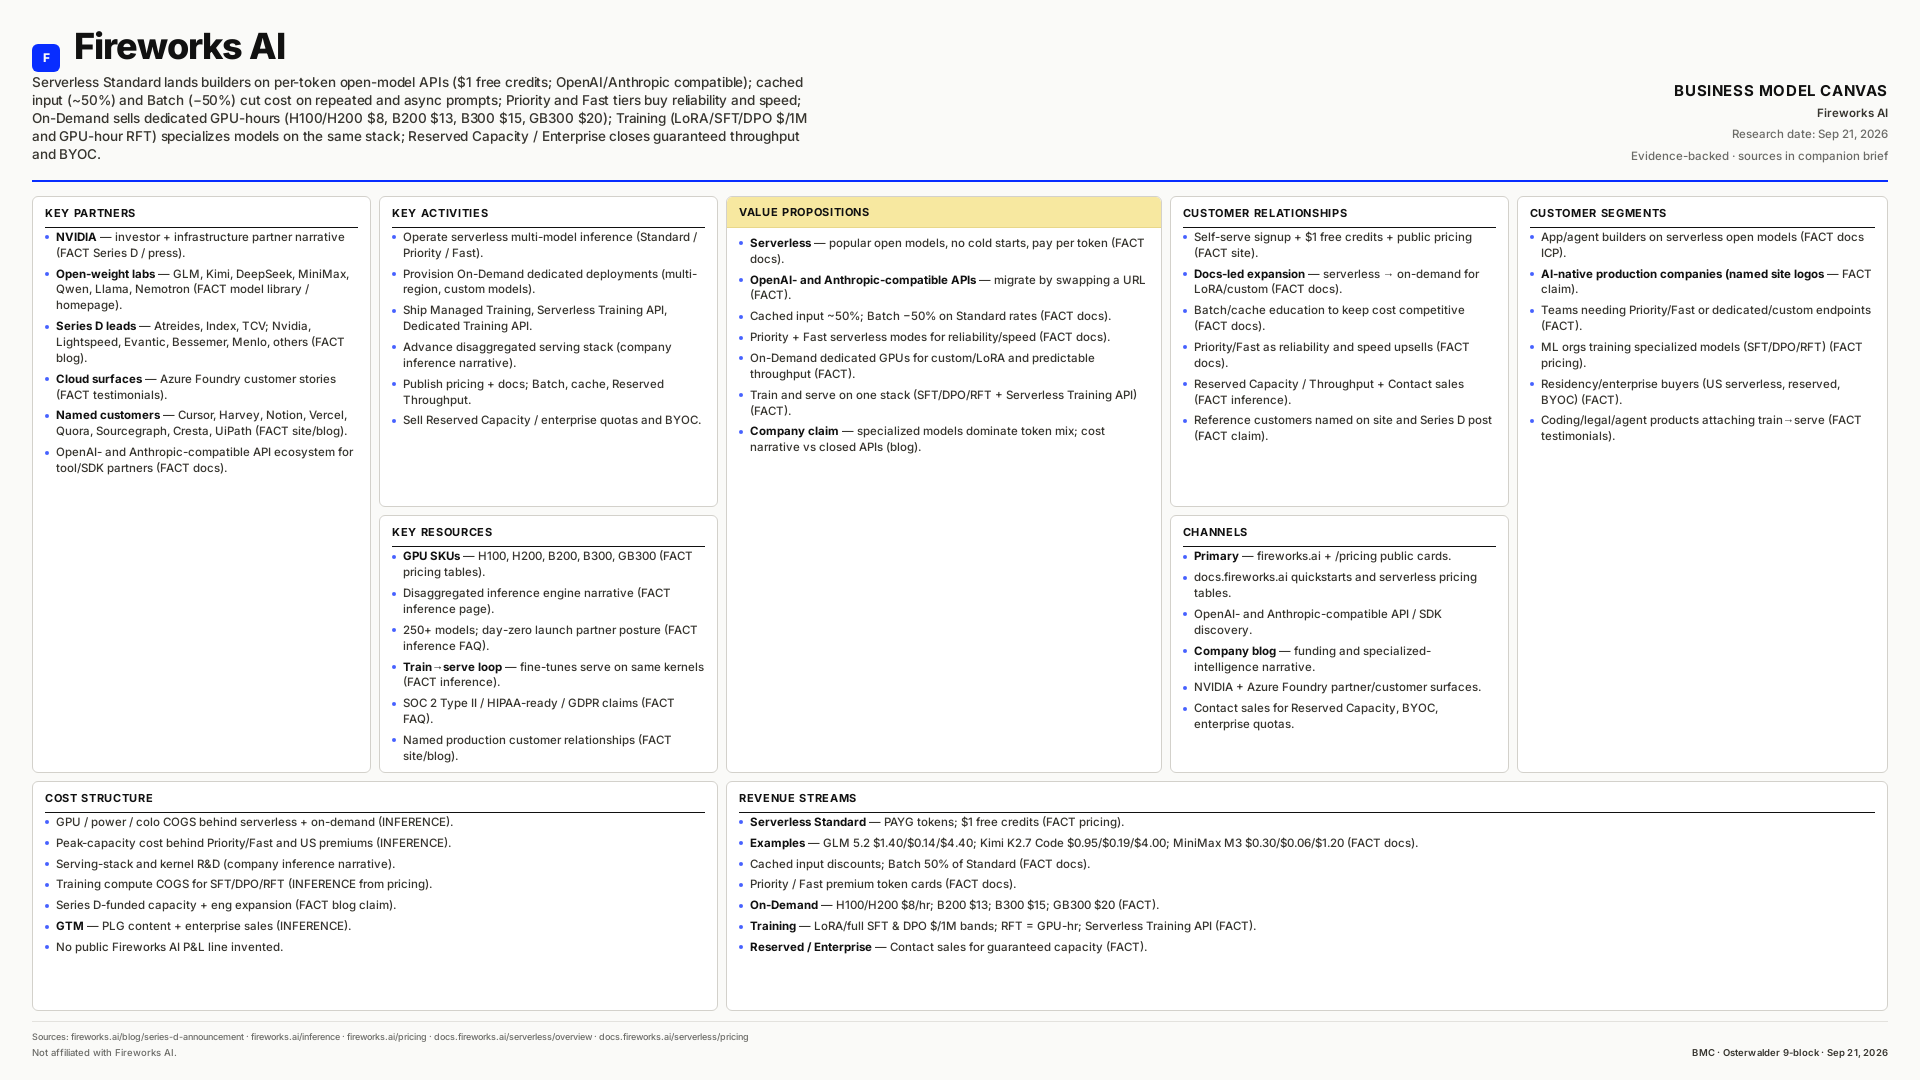
Serverless Standard lands builders on per-token open-model APIs ($1 free credits; OpenAI/Anthropic compatible); cached input (~50%) and Batch (−50%) cut cost on repeated and async prompts; Priority and Fast tiers buy reliability and speed; On-Demand sells dedicated GPU-hours (H100/H200 $8, B200 $13, B300 $15, GB300 $20); Training (LoRA/SFT/DPO $/1M and GPU-hour RFT) specializes models on the same stack; Reserved Capacity / Enterprise closes guaranteed throughput and BYOC.
Click any of the 9 blocks below for a plain-language story of how that part of the model works for Fireworks AI — and how it connects to the others.
Static handout preview — use Downloads in the top bar for PDF, PNG, poster HTML, or the research brief. The interactive canvas above is the primary experience.