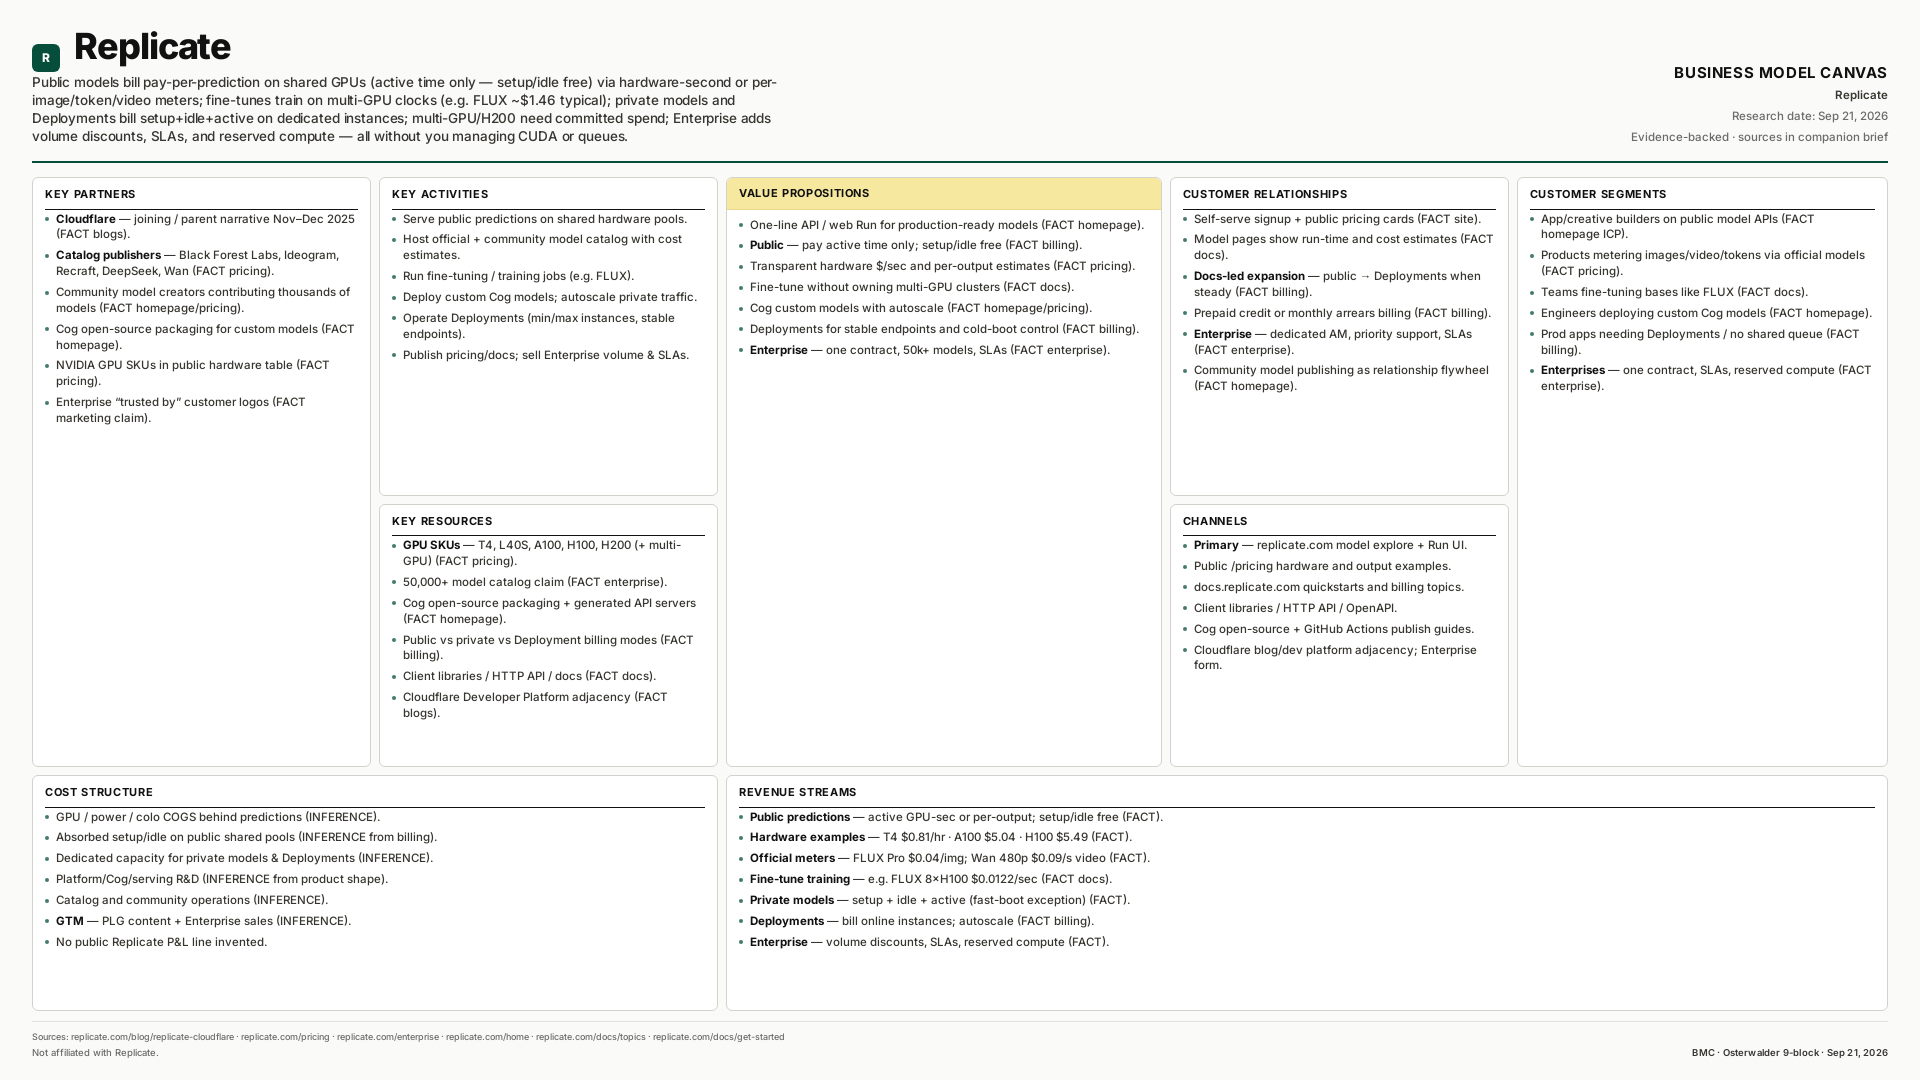
Public models bill pay-per-prediction on shared GPUs (active time only — setup/idle free) via hardware-second or per-image/token/video meters; fine-tunes train on multi-GPU clocks (e.g. FLUX ~$1.46 typical); private models and Deployments bill setup+idle+active on dedicated instances; multi-GPU/H200 need committed spend; Enterprise adds volume discounts, SLAs, and reserved compute — all without you managing CUDA or queues.
Click any of the 9 blocks below for a plain-language story of how that part of the model works for Replicate — and how it connects to the others.
Static handout preview — use Downloads in the top bar for PDF, PNG, poster HTML, or the research brief. The interactive canvas above is the primary experience.