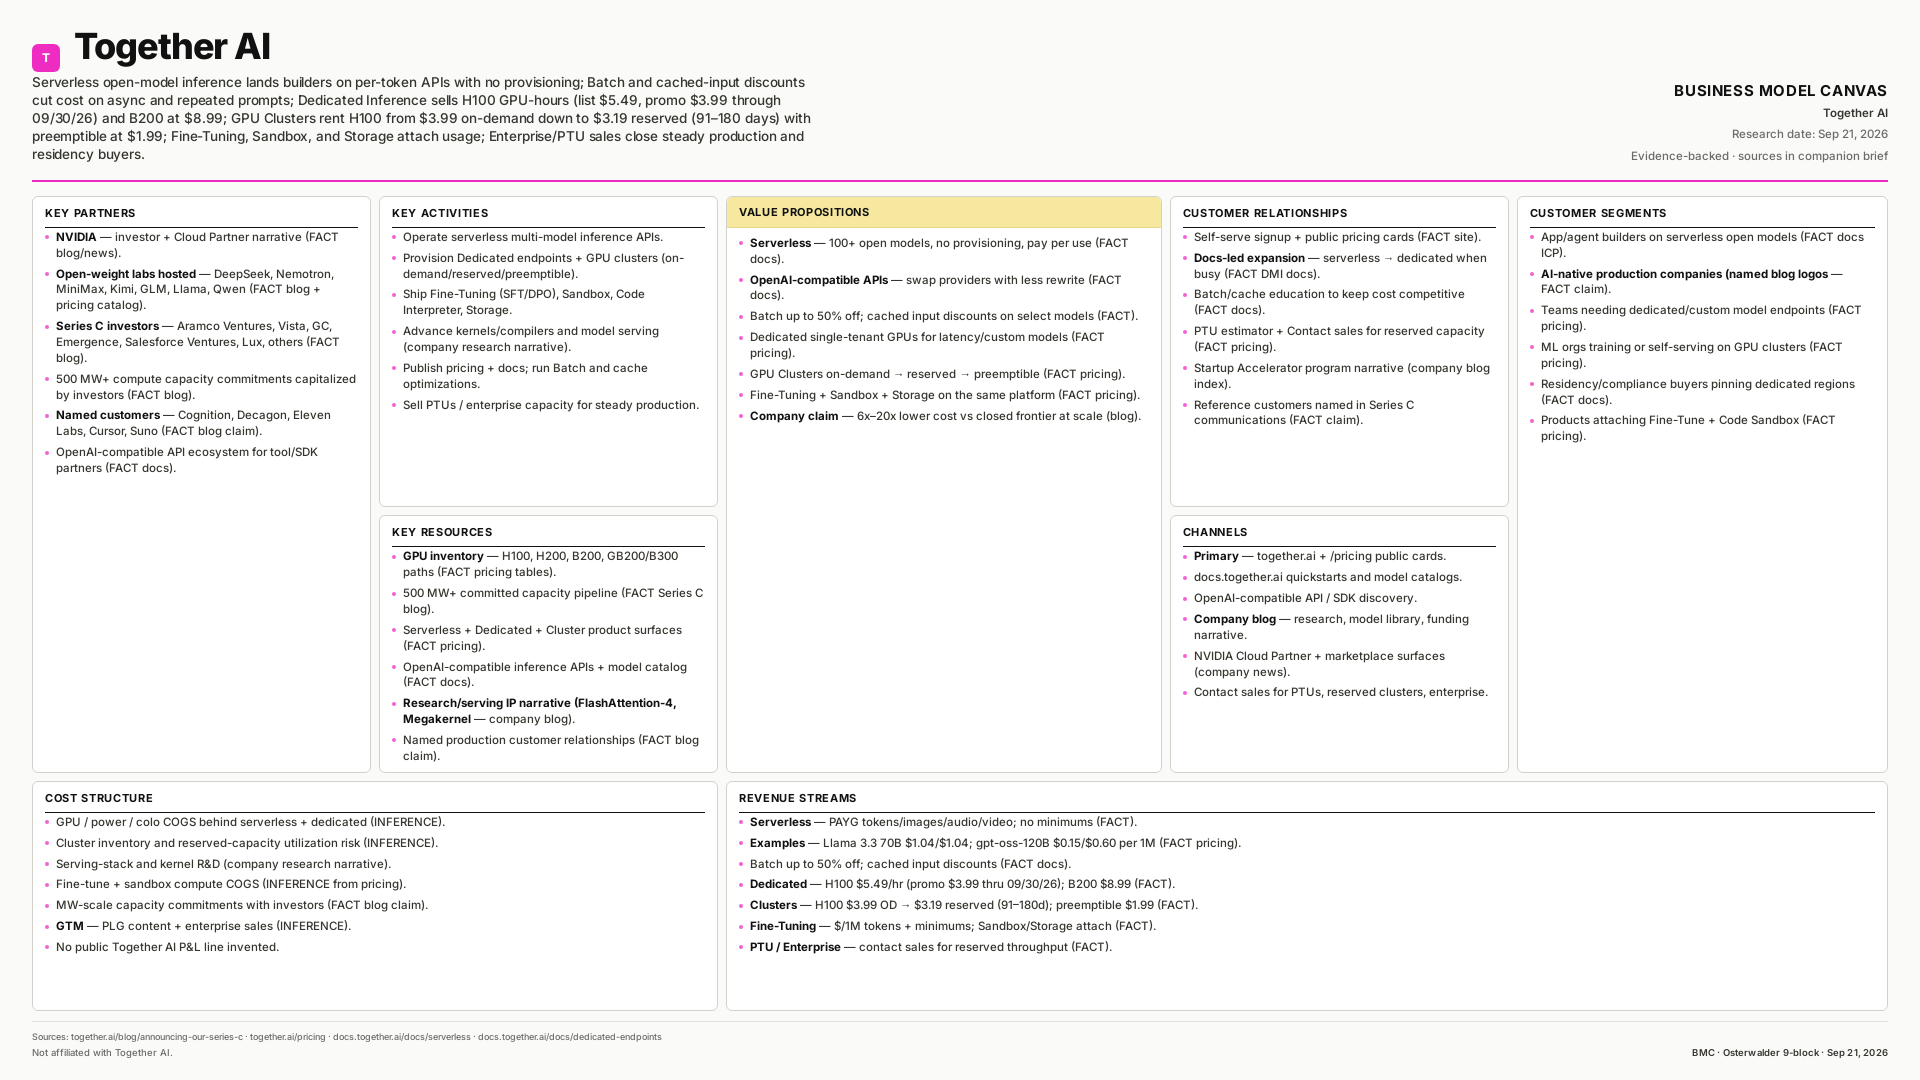
Serverless open-model inference lands builders on per-token APIs with no provisioning; Batch and cached-input discounts cut cost on async and repeated prompts; Dedicated Inference sells H100 GPU-hours (list $5.49, promo $3.99 through 09/30/26) and B200 at $8.99; GPU Clusters rent H100 from $3.99 on-demand down to $3.19 reserved (91–180 days) with preemptible at $1.99; Fine-Tuning, Sandbox, and Storage attach usage; Enterprise/PTU sales close steady production and residency buyers.
Click any of the 9 blocks below for a plain-language story of how that part of the model works for Together AI — and how it connects to the others.
Static handout preview — use Downloads in the top bar for PDF, PNG, poster HTML, or the research brief. The interactive canvas above is the primary experience.